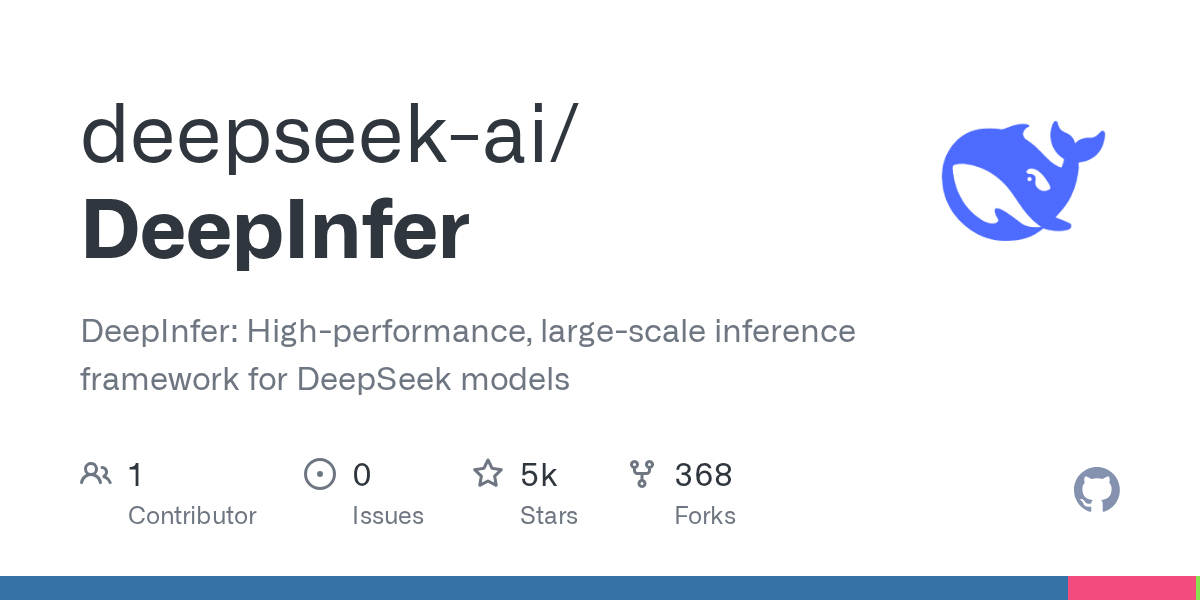
DeepSeek has open-sourced DeepInfer, a high-performance inference framework designed to serve its large language models at scale. The code went live on GitHub under the company's deepseek-ai organization, giving outside developers direct access to the software DeepSeek uses to run its models.
Inference is the step where a trained model answers a request — the part users actually feel, in latency and cost. By publishing DeepInfer rather than keeping it internal, DeepSeek is handing the AI community a piece of its production stack, in line with the open-weight strategy that made the company a fixture in global AI debates.
What DeepInfer actually is
The GitHub repository describes DeepInfer as a high-performance, large-scale inference framework for DeepSeek models. The project tree includes separate directories for core C source code, clustering, the main deepinfer package, documentation, evaluation tooling, examples and scripts — the shape of a framework meant to be deployed, not just read.
The repository also shows 15 open pull requests, suggesting active, ongoing development rather than a one-off code dump. That cadence matters: inference engines live or die on constant tuning for new hardware and new model versions.
Why open-sourcing the serving layer matters
Model weights get the headlines, but the inference engine decides how cheaply and quickly those weights can answer real traffic. Releasing that layer lets cloud providers, startups and researchers optimize DeepSeek models on their own hardware instead of depending on DeepSeek's own API.
It also raises the pressure on rivals. If DeepSeek's serving stack is free to inspect and improve, competing closed engines have to justify their performance gap more loudly — a dynamic that has already played out around DeepSeek's models themselves.