PC
A hands-on test shows Linux running on Nvidia RTX Spark laptops — but the GPU drops to roughly 780 MHz, cutting AI inference speed to around 35% of Windows.
Search
No phones and 9 stories for “AI inference”
PC
A hands-on test shows Linux running on Nvidia RTX Spark laptops — but the GPU drops to roughly 780 MHz, cutting AI inference speed to around 35% of Windows.
AI
San Francisco-based Fal has raised $1.3 billion led by Bessemer at a $16 billion valuation, double its worth in April, as demand for AI inference services surges.
AI
Sam Altman stated that having the world's scarce DRAM in personal computers for local inference is a poor use of resources compared to cloud data centers.
AI
Nvidia has joined a $14M Series B in Bengaluru-based Simplismart, which optimises AI inference so companies get more out of the GPUs they already own.
AI
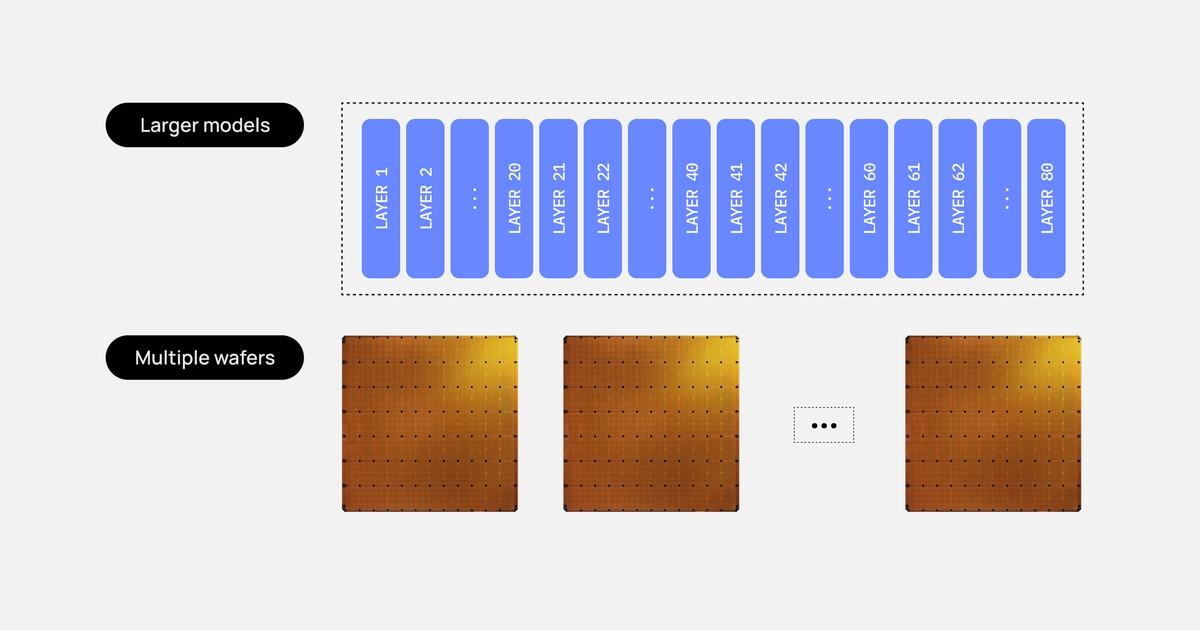
Cerebras has detailed how it spreads 3-trillion-parameter models like Kimi K3 across 59 WSE-3T wafers, keeping weights on-chip and streaming activations between them.
AI
DeepSeek published DeepInfer on GitHub, an open-source inference framework built to run its large language models at scale. The release puts the company's serving stack in developers' hands.