Neural networks may be far easier to understand than the AI field has assumed for years. In a long new essay, Goodfire researcher Nick Cammarata says most neurons in models up to trillions of parameters are already interpretable, and that the outlook for mechanistic interpretability is much better than he had feared. The write-up was surfaced by Techmeme.
The claim matters because interpretability is one of the biggest open problems in AI safety. If researchers can read a network's internal parts directly, they may not need to train a second model just to untangle it first. Cammarata frames this as good news: neural networks, in his words, are already clean.
The case against superposition
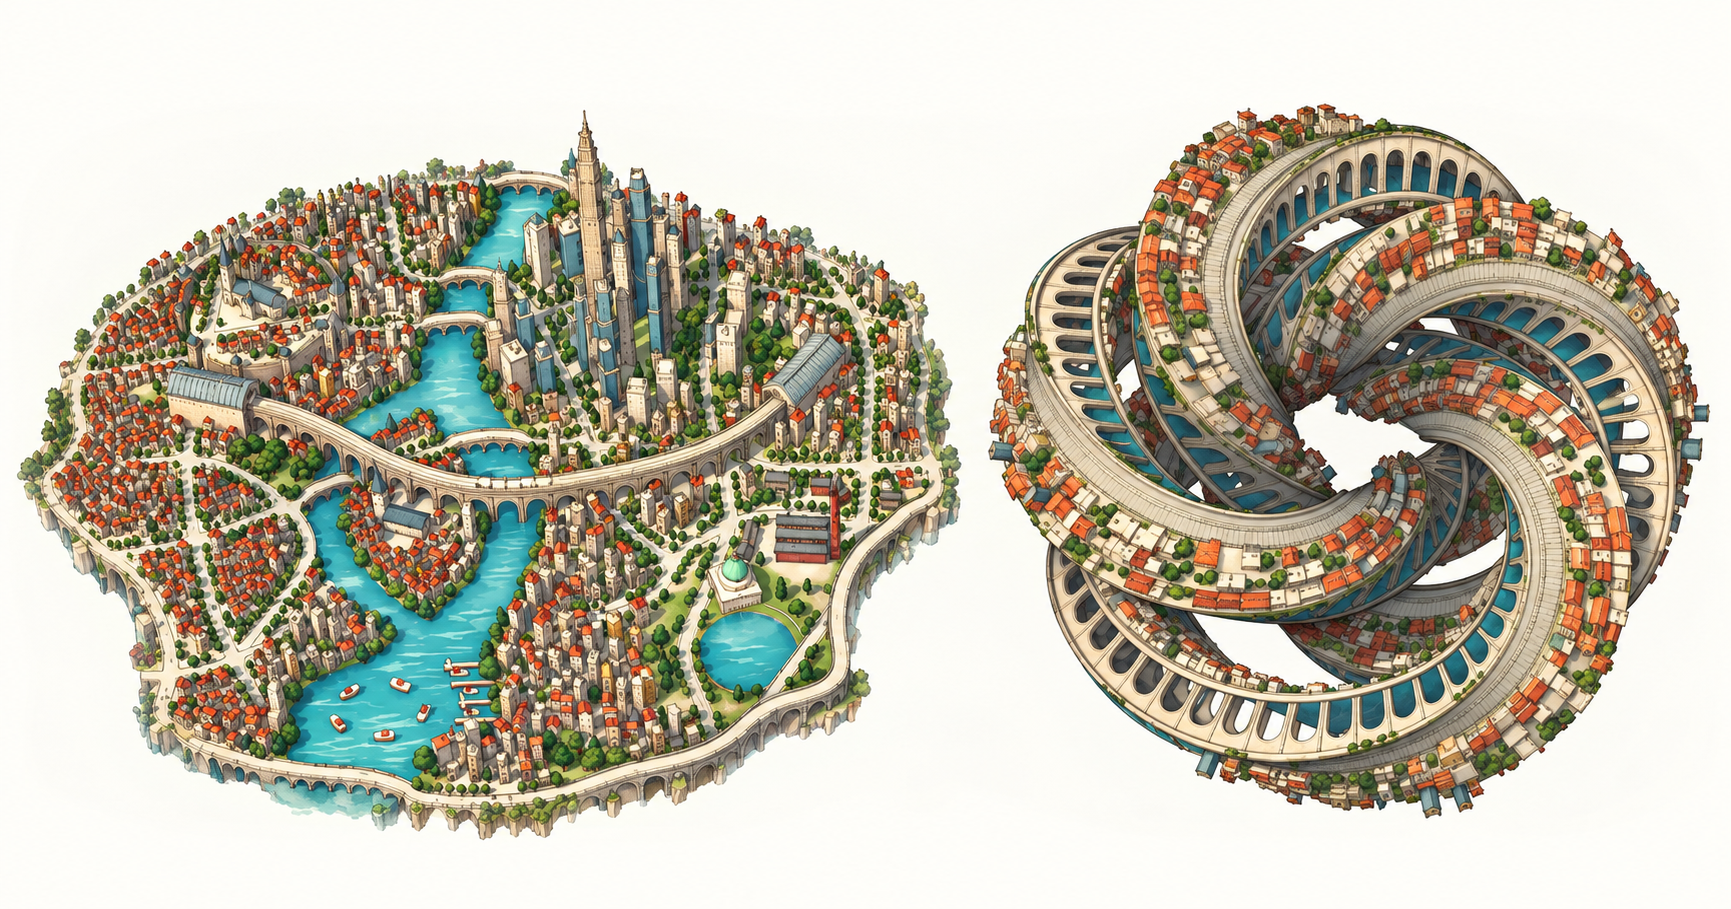
The field's long-standing worry was polysemanticity: neurons that appear to juggle several unrelated jobs. Superposition was the leading explanation, suggesting that when a network runs out of neurons it folds unrelated concepts together, and that the resulting knots are arbitrary and hard to read.
Cammarata now says the canonical evidence for that view was misread. The famous InceptionV1 example, where almost no neurons in the last layer looked interpretable, was caused by architectural problems that made later layers overflow, not by superposition. Weak interpretability tools amplified the confusion.
With ordinary architectural fixes and no change to model size or training data, he reports that 99-100% of neurons in the same last layer are now easily interpretable, and the model is broadly legible end to end. He trained versions across a 300x size range and says they stay legible at every scale.
- Old view: unrelated concepts are packed together, so networks must be untangled before study.
- New claim: what looked like packing is mostly recursive generalization, a less concerning pattern.